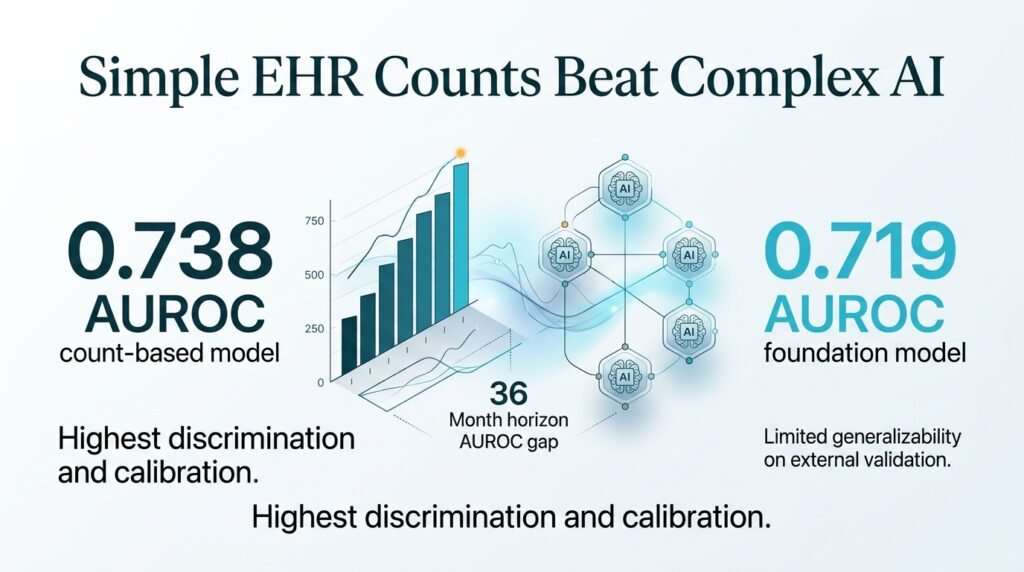
A new study reveals that basic medical record tallies outperform massive clinical AI models at predicting dementia years before diagnosis.
We are told that massive clinical foundation models are the future of medicine. Yet, when tasked with spotting early signs of Alzheimer’s disease, the expensive AI giants got beaten by a simple tally of patient record codes.
This disconnect exposes a major flaw in the current healthcare AI gold rush.
For short-term predictions, simple math beats complex neural networks. Researchers tested these approaches using data from the All of Us Research Program. They looked at patient records at clinically meaningful lead times of 6, 12, 24, and 36 months before an official dementia diagnosis.
The simple math advantage
The study benchmarked traditional count-based models against four prominent pretrained clinical foundation models: CLMBR-T, a GPT-style model, a LLaMA-style model, and Mamba. Across all timeframes, the transparent, count-based representations consistently delivered the highest discrimination and calibration. They proved that tracking the sheer frequency of clinical events is more predictive than trying to model deep semantic relationships in medical notes.
At the longest prediction horizon of 36 months, the count-based model achieved an AUROC of 0.738. The best-performing foundation model lagged slightly behind with an AUROC of 0.719. While the foundation models offered higher sensitivity and better F1 scores at that 36-month mark, they required vastly more computing power to get there.
Why this finding matters
This challenges the assumption that clinical AI must be complex to be useful. For health systems, deploying a count-based model is cheap, transparent, and easy to audit. If basic code tallies perform better than multi-billion-parameter models, hospitals have little reason to adopt expensive, black-box AI for near-term risk screening.
However, both technologies still have a major hurdle to clear.
The generalization trap
When researchers tested both model types on external data from UChicago EHRs using zero-shot evaluation, the performance dropped significantly. Neither the simple counts nor the advanced foundation models generalized well to the new hospital system. This suggests that local data quirks, not model sophistication, remain the true bottleneck in predictive health.
- Count-based models achieved the highest overall discrimination at all lead times of 6, 12, 24, and 36 months.
- At the 36-month mark, the count-based model scored 0.738 AUROC compared to 0.719 for the foundation model.
- Foundation models showed higher sensitivity and F1 scores only at the longest 36-month horizon.
- Both approaches failed to generalize well during external validation at UChicago.
Read the full study on medRxiv.