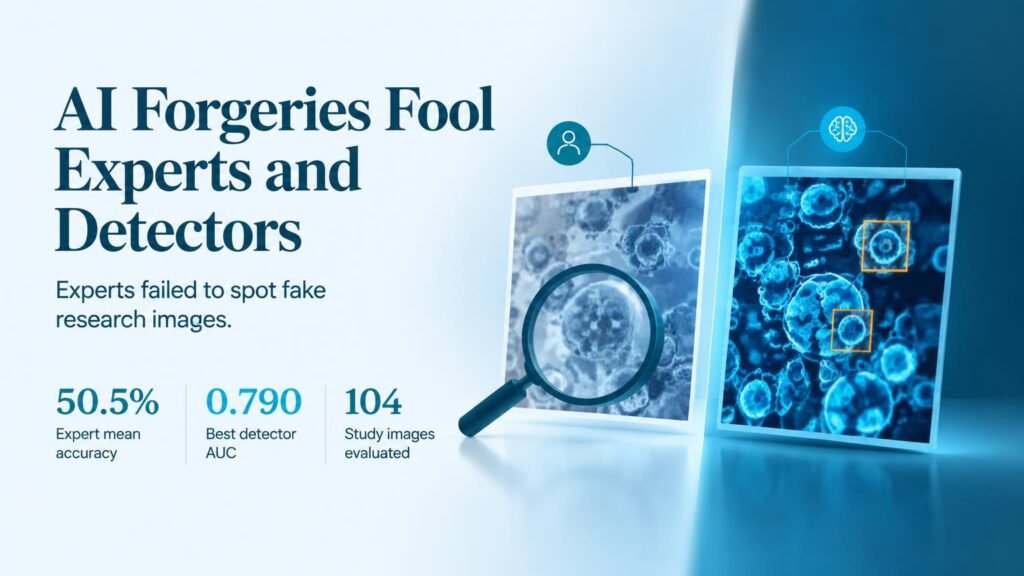
Peer reviewers can no longer reliably spot fake biomedical images, exposing a critical vulnerability in scientific publishing.
Generative AI models can now alter preclinical images convincingly enough to change the core conclusions of a study. A diagnostic trial evaluated how well human eyes and commercial algorithms detect these synthetic manipulations. The results show that traditional peer review is entirely unprepared for AI-generated scientific fraud.
This failure challenges the core assumption that expert scrutiny protects literature from bad data. When fraudulent images pass inspection, fake mechanistic findings can enter published literature and derail downstream drug development.
The Expert Blind Spot
Researchers tested a dataset of 104 western blot and subcutaneous xenograft tumor images. A high-fidelity generative model altered these figures to fabricate therapeutic outcomes. The team then recruited 24 PhD-level expert reviewers to evaluate the image set and identify manipulations.
The human experts performed no better than random guessing.
Their mean diagnostic accuracy was 50.5% with a standard deviation of 6.9%. Expert credentials offered zero advantage in spotting synthetic alterations in standard laboratory figures.
Software Falls Short
Publishers looking to software for a quick fix will not find one here. The study evaluated commercial AI detection software against the same figure set to see if automated systems could succeed where humans failed.
The best-performing commercial detector achieved an area under the curve (AUC) of 0.790, with a 95% confidence interval of 0.695 to 0.885. While automated screening outperformed human reviewers, an AUC of 0.790 represents only moderate discrimination. It creates a false sense of security while letting sophisticated forgeries slip through.
Key Findings
- Tested dataset contained 104 modified western blot and xenograft tumor images.
- Human performance: 24 PhD-level reviewers scored a mean accuracy of 50.5% (SD 6.9%).
- Automated performance: Best commercial AI tool reached an AUC of 0.790 (95% CI 0.695-0.885).
Rethinking Integrity Verification
This study demonstrates that visual inspection of published figures is officially obsolete. If PhD-level scientists perform at coin-flip levels, relying on reviewers to catch visual fraud is a policy failure. At the same time, commercial detection algorithms are not yet reliable enough to automate image auditing at scale.
The study has clear boundaries. It evaluated 104 images produced by a single generative model architecture, meaning real-world performance may vary across different image types and synthesis techniques. Nevertheless, the immediate operational takeaway is clear: journals must demand unedited, original raw data files rather than relying on visual screening of final figures.
Read the full study in the Journal of Medical Internet Research.